Monitoring, Logging & Alerting: Building Observable Production Systems
You deploy code. It crashes at 3 AM. You get paged. You have 5 minutes of logs. Good luck.
Observable systems let you understand what happened before it crashes. This guide covers the three pillars: metrics, logs, and traces.
The Three Pillars of Observability#
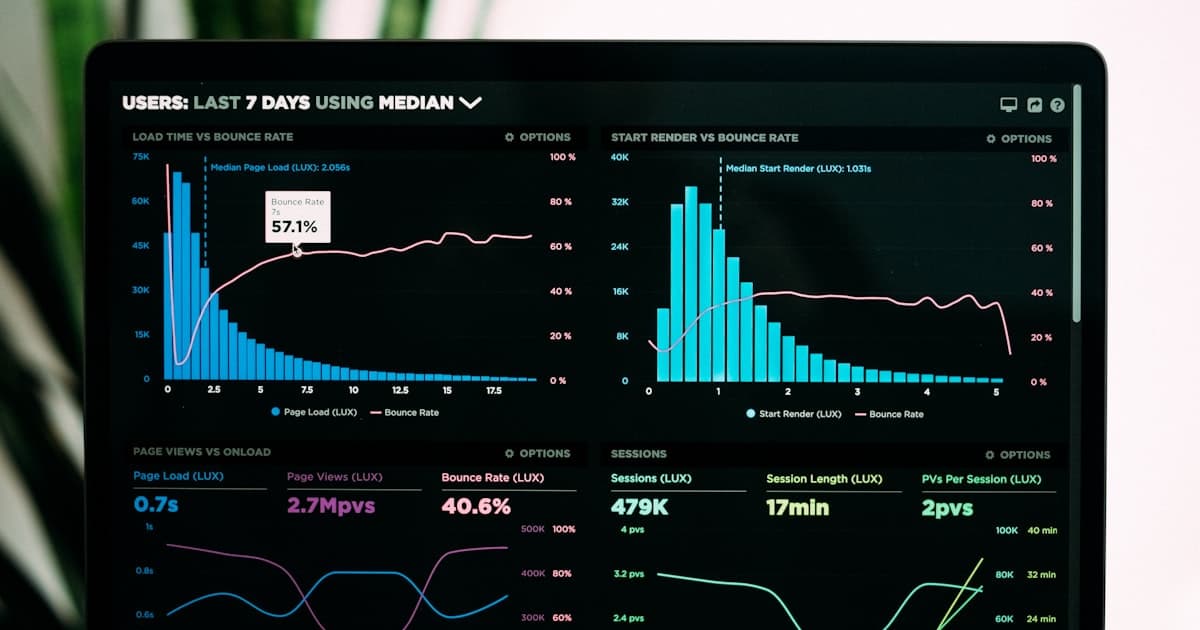
Metrics: Numbers Over Time#
Response time: 45ms → 50ms → 48ms (over seconds)
Error rate: 0.1% → 0.5% → 2% (spike detected!)
CPU usage: 30% → 60% → 95% (trending up)
Store in time-series database (Prometheus, InfluxDB).
Logs: Events & Context#
[2025-01-16 03:14:22] ERROR: Database connection failed
    User: 42
    Endpoint: POST /api/orders
    Error: connection timeout after 5s
    Stack trace: ...
Store in centralized logging (ELK, Splunk, DataDog).
Traces: Request Journey#
Request → API (10ms) → Cache (1ms) → DB (50ms) → API response (65ms)
              ├─ Cache miss (retry once)
              └─ DB slow query detected
Store in tracing system (Jaeger, Datadog, New Relic).
1. Metrics with Prometheus#
Prometheus scrapes metrics from applications:
# prometheus.yml
global:
  scrape_interval: 15s

scrape_configs:
  - job_name: 'myapp'
    static_configs:
      - targets: ['localhost:8080']
Application exposes metrics endpoint:
# Flask + Prometheus
from prometheus_client import Counter, Histogram, Gauge

# Counter: Increments only
request_count = Counter('requests_total', 'Total requests', ['method', 'endpoint'])

# Histogram: Distribution (latency)
request_latency = Histogram('request_duration_seconds', 'Request latency')

# Gauge: Current value
active_connections = Gauge('active_connections', 'Active connections')

@app.route('/api/orders', methods=['POST'])
def create_order():
    request_count.labels(method='POST', endpoint='/api/orders').inc()

    with request_latency.time():
        active_connections.inc()
        try:
            order = Order.create(request.json)
            return {"id": order.id}, 201
        finally:
            active_connections.dec()
Prometheus collects metrics:
requests_total{method="POST",endpoint="/api/orders"} 1234
request_duration_seconds_bucket{le="0.1"} 100
request_duration_seconds_bucket{le="0.5"} 1100
request_duration_seconds_bucket{le="1.0"} 1200
active_connections 42
2. Dashboards with Grafana#
Visualize Prometheus metrics:
{
  "dashboard": {
    "title": "Application Metrics",
    "panels": [
      {
        "title": "Request Rate",
        "targets": [
          {
            "expr": "rate(requests_total[5m])"
          }
        ],
        "type": "graph"
      },
      {
        "title": "P95 Latency",
        "targets": [
          {
            "expr": "histogram_quantile(0.95, request_duration_seconds)"
          }
        ]
      },
      {
        "title": "Error Rate",
        "targets": [
          {
            "expr": "rate(requests_total{status=~\"5..\"}[5m])"
          }
        ]
      }
    ]
  }
}
Grafana dashboard shows:
┌─────────────────────────────────────────────┐
│ Request Rate      │ P95 Latency    │ Errors │
│ 1,234 req/s       │ 125ms          │ 0.2%   │
├─────────────────────────────────────────────┤
│ Response Time (5m)                          │
│ ████████████░░░░░░░ 45ms                   │
├─────────────────────────────────────────────┤
│ Status Codes (pie chart)                    │
│ 200: 98.5%  │ 5xx: 0.2%  │ 4xx: 1.3%     │
└─────────────────────────────────────────────┘
3. Alerting Rules#
Alert when metrics cross thresholds:
# prometheus-alerts.yml
groups:
  - name: application
    rules:
      # Alert if error rate > 5%
      - alert: HighErrorRate
        expr: |
          (rate(requests_total{status=~"5.."}[5m]) /
           rate(requests_total[5m])) > 0.05
        for: 5m
        annotations:
          summary: "High error rate detected"
          description: "Error rate is {{ $value | humanizePercentage }}"

      # Alert if P95 latency > 500ms
      - alert: HighLatency
        expr: |
          histogram_quantile(0.95,
            rate(request_duration_seconds_bucket[5m])) > 0.5
        for: 10m
        annotations:
          summary: "High latency detected"

      # Alert if CPU > 85%
      - alert: HighCPU
        expr: node_cpu_usage > 0.85
        for: 5m
Alert routing (Alertmanager):
# alertmanager.yml
route:
  receiver: 'default'
  group_by: ['alertname']
  group_wait: 10s
  group_interval: 10s
  repeat_interval: 1h

  routes:
    # Critical errors → PagerDuty immediately
    - match:
        severity: critical
      receiver: 'pagerduty'
      group_wait: 5s

    # Warnings → Slack
    - match:
        severity: warning
      receiver: 'slack'
      group_wait: 30s

receivers:
  - name: 'pagerduty'
    pagerduty_configs:
      - service_key: '{{ secrets.pagerduty_key }}'

  - name: 'slack'
    slack_configs:
      - api_url: '{{ secrets.slack_webhook }}'
        channel: '#alerts'
        title: 'Alert: {{ .GroupLabels.alertname }}'
4. Centralized Logging#
Application logs to stdout:
import logging
import json

# Structured logging
logger = logging.getLogger(__name__)

@app.route('/api/orders')
def create_order():
    logger.info(json.dumps({
        "event": "order_created",
        "user_id": 42,
        "order_id": 1234,
        "total": 99.99,
        "timestamp": datetime.now().isoformat()
    }))
Container/Kubernetes logs are collected:
# Docker logs
docker logs myapp

# Kubernetes logs
kubectl logs deployment/myapp --follow

# Forwarded to ELK/Splunk
Query logs:
search: status="error" service="api" user_id=42
fields: timestamp, error_code, stack_trace
stats: count() by error_code
5. Distributed Tracing#
Track request across services:
from opentelemetry import trace, metrics
from opentelemetry.exporter.jaeger.thrift import JaegerExporter
from opentelemetry.sdk.trace import TracerProvider
from opentelemetry.sdk.trace.export import BatchSpanProcessor

# Configure Jaeger
jaeger_exporter = JaegerExporter(
    agent_host_name="localhost",
    agent_port=6831,
)
trace.set_tracer_provider(TracerProvider())
trace.get_tracer_provider().add_span_processor(
    BatchSpanProcessor(jaeger_exporter)
)

tracer = trace.get_tracer(__name__)

@app.route('/api/orders')
def create_order():
    with tracer.start_as_current_span("create_order") as span:
        span.set_attribute("user_id", request.json["user_id"])

        # Nested span: database operation
        with tracer.start_as_current_span("db.insert") as db_span:
            db_span.set_attribute("table", "orders")
            order = Order.create(request.json)

        # Nested span: cache write
        with tracer.start_as_current_span("cache.set") as cache_span:
            cache.set(f"order:{order.id}", order.to_dict())

        return {"id": order.id}, 201
Jaeger UI shows trace:
Request: POST /api/orders (total: 65ms)
├─ create_order (65ms)
│  ├─ db.insert (50ms)  ← Slow!
│  ├─ cache.set (2ms)
│  └─ return (5ms)
Can spot bottlenecks visually.
Key Metrics to Monitor#
| Metric | Threshold | Alert |
|---|---|---|
| Error rate | > 1% | P0 |
| P99 latency | > 500ms | P1 |
| Memory usage | > 90% | P1 |
| Disk usage | > 85% | P2 |
| CPU usage | > 80% | P2 |
| Active connections | > threshold | Warn |
| Queue depth | > threshold | Warn |
Checklist#
- Metrics: Counter, Histogram, Gauge types
- Scrape metrics with Prometheus (15s interval)
- Visualize with Grafana dashboard
- Alert rules (error rate, latency, resource)
- Alert routing (Slack, PagerDuty, email)
- Centralized logging (ELK, Splunk)
- Structured logs (JSON format)
- Distributed tracing (Jaeger, Datadog)
- Trace propagation (parent-child spans)
- Monitor alert fatigue (tune thresholds)
Conclusion#
Observability is the difference between responding in 5 minutes vs 30 minutes. Metrics detect patterns. Logs provide context. Traces reveal the path.
Start with metrics + dashboards. Add logging next. Traces are for advanced debugging.
You can't fix what you can't see.
Debugging production incidents with too little visibility? Book a 15-minute call.
FAQ
Metrics, logs, or traces — where should I start?
Metrics and dashboards first — they're cheapest to set up and catch most issues. Add structured logging next for context. Distributed tracing last, once you have multiple services and need to see a request's full path.
How do I stop alert fatigue from useless pages?
Alert on symptoms (error rate, latency, saturation) that affect users, not on every internal metric crossing a threshold — an alert nobody acts on trains the on-call to ignore all alerts.
What's the real cost of poor observability?
Mean time to resolution. Five minutes of logs at 3 AM turns a 5-minute fix into a multi-hour incident — the cost shows up as downtime, not as a line item on the tooling bill.
RelatedArticles
Continue exploring production engineering guides, systems architecture, and cloud patterns.